Create Transcription Node
The Create Transcription node transcribes audio files to text using OpenAI's Whisper model.
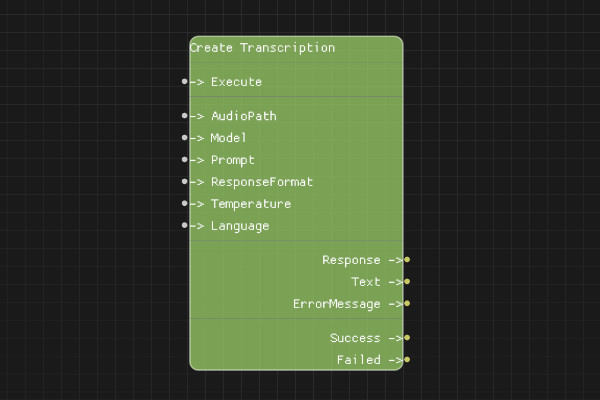
Description
The Create Transcription node converts speech in an audio file to text using OpenAI's Whisper transcription model. It supports various audio formats and can transcribe in multiple languages.
Execution Inputs
- Execute (execution): Triggers the transcription request
Variable Inputs
- AudioPath (string): Path to the audio file to transcribe
- Model (string, optional): Model to use. Must be "whisper-1" (default: "whisper-1")
- Prompt (string, optional): Optional text prompt to guide the transcription (e.g., proper nouns, technical terms)
- ResponseFormat (string, optional): Format of the response. Must be "json", "text", "srt", "verbose_json", or "vtt" (default: "json")
- Temperature (float, optional): Sampling temperature between 0 and 1 (default: 0)
- Language (string, optional): Language code (e.g., "en", "es", "fr"). If not specified, language is auto-detected
Execution Outputs
- Success (execution): Execution continues here if the request succeeded
- Failed (execution): Execution continues here if the request failed
Variable Outputs
- Response (string): Full JSON response from the API
- Text (string): The transcribed text
- ErrorMessage (string): Error message if request failed
Special Notes
- Requires a valid API key configured via Set API Key node
- Audio file must be in a supported format (mp3, mp4, mpeg, mpga, m4a, wav, webm)
- Maximum file size is 25MB
- The Prompt can help with proper nouns, technical terms, or context
- Language auto-detection works well but specifying language can improve accuracy
- ResponseFormat "text" returns plain text, "json" returns structured data
Example Usage
Transcribe an audio file:
- Set AudioPath to "audio/recording.mp3"
- Set Model to "whisper-1"
- Set ResponseFormat to "text"
- Connect Execute to transcribe
- Use Text output to get the transcription
Transcribe with language and prompt:
- Set AudioPath to "audio/meeting.mp3"
- Set Language to "en"
- Set Prompt to "John Smith, Sarah Johnson, Q4 earnings"
- Connect Execute to transcribe
Flow Download Example
Placeholder for flow download example
Additional Pictures
Placeholder for additional node images and examples